The Enterprise AI-Invisibility Audit
Where Pipeline Leaks Before the Demo
Executive summary
Your company may be visible in search results and still be invisible during the most important part of the buying journey.
Table of Contents
- The Enterprise AI-Invisibility Audit Framework
- The Five Core Metrics
- The Audit Scorecard
- The Enterprise AI-Invisibility Audit Process
- The Evidence Architecture Required for Enterprise Visibility
- The Competitive Default Problem
- Enterprise AI-Invisibility by Buyer Stage
- The 90-Day Enterprise AI-Invisibility Recovery Plan
- C-Suite Scorecard
- What the Audit Does Not Claim
- Rakesh’s Operating Perspective
- Frequently Asked Questions
An enterprise buyer can ask ChatGPT, Perplexity, Google AI Overviews, Gemini, or Claude to:
- Define a category
- Compare vendors
- Identify alternatives
- Evaluate implementation risk
- Check security and compliance
- Find integration options
- Build a shortlist
- Recommend a platform for a specific use case
If your company is missing from those answers, the buyer may never reach your website.
If your company appears but is described inaccurately, the buyer may reject you for a problem you do not have.
If a competitor is repeatedly cited while your own evidence is absent, the competitor becomes the default reference point before sales ever enters the conversation.
That is the enterprise AI-invisibility problem.
The solution is not to publish more generic content or add unsupported schema. It is to determine exactly where your company disappears:
Buyer question
→ AI answer
→ Brand inclusion or absence
→ Source selection
→ Evidence quality
→ Technical retrieval
→ Commercial consequence
The Enterprise AI-Invisibility Audit turns that chain into a measurable diagnostic.
If the buyer asks the question and your company is not in the answer set, your pipeline problem began before the demo.
What enterprise AI invisibility means
Enterprise AI invisibility is the observed absence, weak representation, or inaccurate description of a company across a defined set of commercial AI-search prompts.
It has three forms.
1. Brand absence
The company is not mentioned when buyers ask relevant category, comparison, integration, implementation, or problem-based questions.
2. Evidence absence
The company is mentioned, but the AI answer engine does not cite or link to the company’s strongest supporting evidence.
3. Representation failure
The company appears, but the answer misstates:
- Product capabilities
- Market focus
- Deployment model
- Security posture
- Integrations
- Pricing boundaries
- Geographic coverage
- Customer fit
- Implementation requirements
These forms require different responses.
| Invisibility type | What the buyer experiences | Typical response |
|---|---|---|
| Brand absence | The company does not enter the shortlist | Build category and use-case evidence |
| Evidence absence | The company is named without supporting proof | Publish accessible, specific proof assets |
| Representation failure | The company is described inaccurately | Correct entity inconsistencies and public evidence |
| Technical retrieval failure | Important pages cannot be reliably retrieved | Repair crawlability, rendering, status, links, and access |
| Competitive displacement | A competitor becomes the default answer | Analyze source patterns and close evidence gaps |
Why this matters to CEOs, CMOs, and founders
You are not investing in visibility for its own sake.
You are trying to influence:
- Which companies enter the shortlist
- Which vendors appear credible
- Which solutions buyers compare
- Which risks buyers investigate
- Which products sales teams must explain
- Which competitors become category defaults
- How much paid acquisition is required to recover lost demand
Traditional SEO reporting often tells you:
- Rankings
- Impressions
- Clicks
- Sessions
- Backlinks
- Conversions
Those metrics remain useful. They are not sufficient.
An enterprise buyer may receive a complete category explanation from an AI answer engine without clicking any vendor result. That means your company can lose consideration without a measurable decline in website sessions.
The audit therefore adds five questions:
- Is the company present for the right commercial questions?
- Is the company represented accurately?
- Are the company’s strongest pages cited?
- Can answer systems retrieve the critical evidence?
- Does improved representation connect to qualified pipeline?
The buyer does not need to visit your website to form an opinion about your company.
The Enterprise AI-Invisibility Audit Framework
The audit examines six connected layers.
Layer 1: Commercial prompt demand
Layer 2: Brand and competitor representation
Layer 3: Owned evidence completeness
Layer 4: Technical retrieval accessibility
Layer 5: External entity corroboration
Layer 6: Pipeline and revenue connection
Layer 1: Commercial prompt demand
The audit starts with buyer questions, not keywords.
A prompt portfolio should include:
- Category definition
- Problem diagnosis
- Vendor comparison
- Alternative evaluation
- Integration assessment
- Security and compliance
- Implementation and migration
- Pricing and procurement
- Use-case selection
- Executive business case
Example prompt categories
| Prompt category | Buyer question |
|---|---|
| Category | What is the best observability platform for a distributed engineering organization? |
| Problem | How can a SaaS company reduce alert fatigue across multiple environments? |
| Comparison | Which platforms compare with the leading enterprise observability tools? |
| Integration | Which observability tools integrate with Kubernetes, AWS, and Datadog workflows? |
| Security | What should an enterprise evaluate before adopting a SaaS security platform? |
| Implementation | How long does it take to migrate from one enterprise SaaS platform to another? |
| Executive | Which solution offers the strongest balance of implementation effort and business value? |
The exact prompts should be adapted to the company’s market, product, buyer roles, and sales motion.
Layer 2: Brand and competitor representation
For each prompt, record:
- Whether the company is named
- Whether the company is cited
- Whether an owned page is linked
- Whether a third-party source is used
- Which competitors appear
- Whether the response is accurate
- Whether the answer supports the buyer’s decision
- Whether the answer contains material omissions
Representation classification
| Classification | Meaning |
|---|---|
| Directly represented | Company is named in a relevant context |
| Cited | Company or its evidence is linked as a source |
| Indirectly represented | Company evidence is used without a clear commercial mention |
| Absent | Company does not appear |
| Misrepresented | Company appears with a material factual error |
| Irrelevant inclusion | Company appears but does not match the prompt |
Layer 3: Owned evidence completeness
The audit examines whether the website contains accessible, specific, current evidence for the questions buyers ask.
Evidence categories
| Evidence category | Buyer uncertainty resolved |
|---|---|
| Category definition | What problem does this product category solve? |
| Product scope | What does the product do and not do? |
| Use cases | Which workflows and teams does it support? |
| Integrations | How does it connect to the existing stack? |
| Security | What controls, certifications, and boundaries apply? |
| Implementation | What does deployment require? |
| Migration | What changes when replacing an existing solution? |
| Customer evidence | Has the product worked in a comparable context? |
| Pricing and procurement | How should the company evaluate cost and buying requirements? |
| Author and reviewer signals | Who can support the claims being made? |
Evidence completeness test
For each priority prompt, ask:
- Does an owned page answer the question?
- Is the answer direct and specific?
- Is the scope clear?
- Are limitations disclosed?
- Is the evidence current?
- Is the page linked from relevant hubs?
- Is the page technically accessible?
- Does structured data match visible content?
- Is there a clear next step?
- Can sales use the page during evaluation?
Layer 4: Technical retrieval accessibility
A page cannot support AI-assisted discovery if critical information is difficult to retrieve.
The technical audit checks:
- HTTP status
- Final URL
- Redirect chain
- Canonical
- Robots directives
- Sitemap inclusion
- Internal links
- Initial HTML content
- Rendered DOM content
- Metadata
- Visible headings
- Structured data
- Response time
- Server errors
- WAF and bot restrictions
- Content parity between source and browser-rendered page
Source versus rendered content test
The audit compares:
Initial HTTP response
versus
Browser-rendered DOM
The initial response should contain the essential commercial record:
- Page title
- Canonical URL
- H1
- Primary definition
- Core product or category copy
- Important internal links
- Author or reviewer information where relevant
- Matching structured data
A browser can display content after JavaScript runs. That does not prove every retrieval system receives the same content.
If your most important proof exists only after hydration, it is not reliably available to every evaluator.
Layer 5: External entity corroboration
AI systems interpret companies through a broader information ecosystem than the company website alone.
Relevant sources may include:
- Official documentation
- Review platforms
- Partner directories
- Industry publications
- Customer references
- Technical communities
- Public repositories
- Standards organizations
- Conference pages
- Podcast pages
- Executive profiles
- Professional networks
- Analyst and comparison pages
The audit does not recommend manipulating these sources. It recommends factual consistency.
External consistency checks
Compare:
- Company name
- Product names
- Category description
- Industry served
- Integration claims
- Security claims
- Geographic coverage
- Leadership and author information
- Customer references
- Product status
- Pricing language
Inconsistency creates entity ambiguity.
Layer 6: Pipeline and revenue connection
Visibility is not the final outcome.
Connect audit observations with:
- Branded demand
- Organic landing pages
- Demo and trial conversions
- Account engagement
- Self-reported discovery
- Sales-call notes
- Opportunity creation
- Pipeline value
- Win and loss reasons
- Acquisition cost
- Paid-recapture patterns
The strongest audit output does not simply say:
“Your company appeared more often.”
It says:
“These buyer questions improved, these evidence gaps were repaired, these accounts engaged, and this opportunity-level evidence was observed.”
The Five Core Metrics
Prompt-level company absence rate
Prompt-level company absence rate measures how often the company is absent from eligible commercial prompts.
Prompt-level company absence rate =
Eligible prompts without a relevant company mention
÷
Total eligible prompts tested
× 100
Example
If the company is absent from 42 of 100 eligible prompts:
42 ÷ 100 × 100 = 42%
This is a prompt-observation metric, not a forecast of lost revenue.
Competitor default rate
Competitor default rate measures how often one or more competitors appear as the preferred or default answer when the company is absent or weakly represented.
Competitor default rate =
Eligible prompts where a competitor is presented as a default option
÷
Eligible prompts tested
× 100
You may also calculate a company-specific displacement rate:
Company displacement rate =
Prompts where competitor appears and company is absent
÷
Eligible prompts tested
× 100
Evidence completeness score
Evidence completeness measures whether the company has accessible evidence supporting the questions buyers ask.
Suggested scoring dimensions
Score each dimension from 0 to 2:
- Category definition
- Product scope
- Use-case evidence
- Integration evidence
- Security and trust evidence
- Implementation guidance
- Customer or outcome proof
- Author or reviewer credibility
- Internal linking
- Technical accessibility
Evidence completeness score =
Total points achieved
÷
Maximum possible points
× 100
With 10 dimensions scored from 0 to 2, the maximum score is 20.
| Score | Interpretation |
|---|---|
| 0 to 39 | Severe evidence deficit |
| 40 to 59 | Material evidence gaps |
| 60 to 79 | Usable but incomplete |
| 80 to 100 | Strong evidence foundation |
These bands are an audit framework, not a market benchmark.
Technical retrieval pass rate
Technical retrieval pass rate measures the percentage of audited priority pages that satisfy the defined technical access contract.
Technical retrieval pass rate =
Priority pages passing all required retrieval checks
÷
Priority pages audited
× 100
Required checks
- Successful status
- Correct canonical
- No unintended noindex
- Present in sitemap where appropriate
- Crawlable internal links
- Primary content in initial HTML
- Valid structured data
- No material source-to-DOM content gap
- Acceptable response behavior
- No blocking access-control failure
High-intent prompt recovery rate
High-intent prompt recovery rate measures whether a previously absent or weak company representation improves after remediation.
High-intent prompt recovery rate =
Previously deficient prompts that meet the recovery condition
÷
Previously deficient prompts retested
× 100
Define the recovery condition before re-testing.
For example:
Recovered prompt =
Company is relevantly mentioned,
answer is materially accurate,
and at least one appropriate evidence source is cited or linked
Stop Funding Channels You Cannot Explain
You do not need another traffic report. You need a defensible view of where qualified demand originates, how it moves through the buying committee, and what your acquisition mix actually costs.
Get the Executive Pipeline DiagnosticThe Audit Scorecard
The five core metrics should be presented together.
| Metric | Baseline | Retest | Change | Confidence | Commercial interpretation |
|---|---|---|---|---|---|
| Prompt-level company absence rate | Is the company missing from priority questions? | ||||
| Competitor default rate | Which competitors become the default answer? | ||||
| Evidence completeness score | Can the website support the claims buyers need? | ||||
| Technical retrieval pass rate | Can priority evidence be retrieved reliably? | ||||
| High-intent prompt recovery rate | Did remediation improve representation? |
Confidence levels
| Confidence | Meaning |
|---|---|
| High | Repeated observations, stable prompts, clear classification, preserved evidence |
| Medium | Useful observations with some sample or classification limitations |
| Low | Small sample, inconsistent environment, or incomplete supporting data |
| Directional | Planning signal requiring further testing |
The Enterprise AI-Invisibility Audit Process
Phase 1: Define the commercial truth set
Before running prompts, define:
- Target category
- Products and modules
- Priority markets
- Buyer roles
- Competitors
- Sales motion
- High-value use cases
- Enterprise risks
- Decision stages
- Relevant sources
- Exclusion rules
Buyer-role prompt map
| Buyer role | Typical question |
|---|---|
| CEO or founder | Which solution will help us scale without increasing operational complexity? |
| CMO | Which platform can improve growth while integrating with our current marketing stack? |
| CTO | Which solution is technically reliable, secure, and scalable? |
| CFO | What are the implementation and operating-cost implications? |
| VP Engineering | How does the product integrate with our infrastructure and workflows? |
| RevOps leader | How does the solution affect data quality, attribution, and process control? |
| Procurement | What evidence is available for risk, security, pricing, and contract review? |
Phase 2: Build the prompt ledger
Each prompt should have a stable ID.
| Field | Required value |
|---|---|
| Prompt ID | Stable identifier |
| Exact prompt | Unmodified test question |
| Category | Category, comparison, integration, and so on |
| Buyer role | Intended evaluator |
| Buying stage | Awareness, evaluation, decision, or validation |
| Geography | Market and locale |
| Language | Prompt language |
| Engine | Tested AI answer engine |
| Test date | Timestamp |
| Response capture | Full response or approved record |
| Company status | Mentioned, cited, absent, or misrepresented |
| Competitors | Named alternatives |
| Sources | Cited domains and pages |
| Reviewer | Person conducting classification |
| Confidence | High, medium, low, or directional |
Prompt stability rule
Do not silently rewrite prompts between baseline and retest.
If a prompt changes, create a new prompt ID.
Phase 3: Run baseline observations
Run the same prompt portfolio across selected engines.
Record:
- Exact response
- Sources
- Company mention
- Competitor mention
- Accuracy
- Missing evidence
- Misclassification
- Prompt variation
- Locale
- Date
- Account state where relevant
Do not treat a single response as a permanent ranking.
Phase 4: Audit owned evidence
Map every priority prompt to:
- Existing answer page
- Product page
- Technical documentation
- Integration page
- Security page
- Customer proof
- Comparison page
- Implementation guide
- Author or reviewer
- Internal links
- Structured data
Evidence gap classifications
| Gap | Description |
|---|---|
| Missing | No relevant owned evidence exists |
| Generic | Evidence exists but does not resolve the buying question |
| Buried | Evidence exists but is difficult to discover |
| Inaccessible | Technical delivery prevents reliable retrieval |
| Outdated | Evidence is no longer current |
| Contradictory | Different pages make inconsistent claims |
| Unverifiable | Claim lacks a credible supporting source |
| Unconnected | Evidence exists but is not linked to the buyer journey |
Phase 5: Score technical retrieval
Test representative pages and every priority commercial page where possible.
Technical audit checklist
| Check | Pass condition |
|---|---|
| Status | Correct 200, 404, or redirect response |
| Canonical | Correct canonical points to intended URL |
| Robots | No unintended blocking or noindex |
| Sitemap | Intended indexable page is included |
| Internal links | Page is reachable through real links |
| Initial HTML | Primary answer and evidence are present |
| Metadata | Title and description match page purpose |
| Structured data | Valid and consistent with visible content |
| Rendering | No material content loss after rendering |
| Response health | Stable response without recurring 5xx or timeout |
| Access controls | Intended crawlers are not unintentionally blocked |
Phase 6: Prioritize remediation
Use a transparent priority formula.
Priority score =
Commercial importance
×
Prompt demand relevance
×
Evidence gap severity
×
Technical accessibility risk
÷
Estimated remediation effort
Score each factor from 1 to 5.
| Factor | 1 | 5 |
|---|---|---|
| Commercial importance | Low-value topic | Directly tied to enterprise pipeline |
| Prompt relevance | Peripheral | Repeated high-intent buyer question |
| Evidence severity | Minor refinement | No credible answer exists |
| Technical risk | Fully accessible | Critical content cannot be retrieved |
| Remediation effort | Extensive | Fast, controlled fix |
Phase 7: Re-test and interpret
Re-test:
- The same prompts
- The same markets
- The same engines where possible
- The same classification rules
- The same evidence categories
Report:
- New company presence
- New citation presence
- Accuracy changes
- Competitor changes
- Source changes
- Technical pass-rate changes
- Qualified engagement
- CRM evidence
- Remaining uncertainty
The Evidence Architecture Required for Enterprise Visibility
A decision-grade evidence page
A strong page should answer one buyer uncertainty.
Recommended structure:
- Direct answer
- Scope and intended audience
- Product or category definition
- How the solution works
- Supported use cases
- Integration requirements
- Security and governance boundaries
- Implementation assumptions
- Limitations and non-fit conditions
- Evidence and references
- Related technical or commercial pages
- Next action
- Review date and responsible owner
Answer-first content template
Direct answer: [Answer the buyer’s question in one concise paragraph. State scope, conditions, and limitations. Avoid unsupported superlatives.]
Then add:
- Who this is for
- What the solution does
- What it does not do
- How it compares
- What implementation requires
- What evidence supports the claim
- What the buyer should evaluate next
Evidence registry
Every important claim should be recorded.
| Field | Example |
|---|---|
| Claim ID | SECURITY-014 |
| Claim | The platform supports SSO through documented identity providers |
| Scope | Enterprise plans using supported configuration |
| Source | Official implementation documentation |
| Owner | Product marketing |
| Reviewer | Solutions engineering |
| Review date | Date of review |
| Next review date | Scheduled date |
| Status | Approved, needs review, retired |
| Used on | URLs and sales assets |
Trust is easier to scale when claims have owners.
Repair the Attribution Layer Before You Scale Acquisition
If original source, landing page, campaign, account, and opportunity fields are incomplete, scaling acquisition will scale uncertainty too.
Audit Your Attribution ArchitectureThe Competitive Default Problem
A competitor’s repeated appearance does not automatically prove algorithmic preference or unfair treatment.
It may indicate:
- More category-defining content
- Stronger third-party references
- Better integration documentation
- More customer proof
- Higher public entity consistency
- More current information
- Greater review coverage
- Clearer terminology
- Stronger technical accessibility
- More frequent independent discussion
The audit should ask:
- Which source domains support the competitor?
- Are those sources independent?
- What buyer questions do they answer?
- Which evidence does your company lack?
- Are your claims consistent across owned and external surfaces?
- Is your product page technically retrievable?
- Does your content answer the exact commercial question?
Do not respond by creating superficial competitor pages. Respond by improving factual, useful, and verifiable evidence.
Enterprise AI-Invisibility by Buyer Stage
| Buying stage | Visibility requirement | Common failure | Recommended asset |
|---|---|---|---|
| Category discovery | Clear category and problem definition | Company has no named category association | Category guide |
| Problem diagnosis | Specific explanation of the operational problem | Generic thought leadership | Problem diagnostic |
| Shortlisting | Clear comparison criteria | Feature parity language | Comparison matrix |
| Technical evaluation | Detailed integrations and architecture | Marketing page lacks implementation detail | Technical guide |
| Risk validation | Security, privacy, compliance, and boundaries | Claims hidden in PDFs | Trust center |
| Business case | Cost, impact, and assumptions | Unsupported ROI promises | Executive calculator |
| Procurement | Clear ownership, scope, and documentation | Sales-only evidence | Procurement resource |
| Implementation | Prerequisites and timeline | Demo-dependent information | Implementation guide |
| Expansion | Use-case and module relationships | Product architecture unclear | Product ecosystem map |
The 90-Day Enterprise AI-Invisibility Recovery Plan
Days 1 to 15: Establish baseline
Work
- Define prompt portfolio
- Select engines and locales
- Identify target competitors
- Capture baseline responses
- Build evidence inventory
- Crawl priority pages
- Audit CRM and branded-demand signals
- Assign claim owners
Deliverables
- Prompt ledger
- Baseline visibility report
- Competitor source map
- Evidence gap inventory
- Technical retrieval report
- Confidence register
Days 16 to 30: Repair high-confidence gaps
Work
- Rewrite category definitions
- Build missing comparison pages
- Add integration evidence
- Expose security and implementation details
- Correct contradictory product claims
- Improve internal links
- Repair canonical and sitemap issues
- Move essential content into initial HTML
- Remove unintended access restrictions
Deliverables
- Priority decision pages
- Evidence registry
- Technical remediation list
- Updated entity map
- Revised internal-link architecture
Days 31 to 60: Expand commercial evidence
Work
- Publish use-case pages
- Publish migration and implementation guides
- Build role-specific executive pages
- Create customer-proof assets where approved
- Add author and reviewer context
- Establish page review dates
- Create downloadable decision frameworks
- Improve external factual consistency
Deliverables
- Buyer-stage content cluster
- Role-specific conversion paths
- Trust and proof library
- Updated citation-ready page templates
- Sales enablement links
Days 61 to 75: Validate representation
Work
- Re-run fixed prompts
- Compare company and competitor representation
- Review answer accuracy
- Identify recurring omissions
- Inspect newly cited pages
- Review branded demand and direct traffic
- Collect sales feedback
Deliverables
- Recovery-rate report
- Source-change report
- Accuracy report
- Sales evidence summary
- New prompt backlog
Days 76 to 90: Connect visibility to pipeline
Work
- Join content IDs to CRM records
- Review account engagement
- Analyze opportunity influence
- Separate visibility from pipeline evidence
- Review paid-recapture patterns
- Calculate attribution completeness
- Prepare executive investment recommendation
Deliverables
- Executive scorecard
- Pipeline evidence report
- Next-quarter remediation backlog
- Research update
- Public methodology notes
Turn Organic Visibility Into a Revenue Operating System
Rakesh helps B2B SaaS marketing teams connect category demand, content influence, AI-search visibility, technical evidence, and CRM pipeline into one measurable operating model.
Build Your Organic Pipeline ScorecardC-Suite Scorecard
Recommended executive dashboard
| Area | metric | Decision supported |
|---|---|---|
| Representation | Company presence rate | Are we entering relevant answers? |
| Source quality | Cited owned-page rate | Are our strongest assets being used? |
| Accuracy | Correct representation rate | Are buyers receiving reliable information? |
| Competition | Competitor default rate | Who becomes the category default? |
| Evidence | Evidence completeness score | What proof is missing? |
| Technical | Retrieval pass rate | Can systems access our proof? |
| Recovery | High-intent prompt recovery rate | Did remediation work? |
| Demand | Organic and branded demand trend | Is visibility reaching the market? |
| Pipeline | Organic-sourced and influenced pipeline | Is visibility connected to opportunities? |
| Data quality | Attribution completeness rate | Can leadership trust the pipeline report? |
Executive interpretation
A strong result may look like:
- Lower company absence rate
- Lower competitor default rate
- Higher evidence completeness
- Higher technical retrieval pass rate
- Better answer accuracy
- More qualified account engagement
- Improved content-to-opportunity association
A strong result does not require every prompt to mention the company.
Relevance matters more than universal presence.
The goal is not to appear in every answer. The goal is to appear when the answer should include you.
What the Audit Does Not Claim
The Enterprise AI-Invisibility Audit does not claim that:
- A citation secures a qualified lead
- A mention proves influence
- Schema forces AI inclusion
- One prompt represents the market
- One engine represents all AI answer engines
- A competitor’s presence proves manipulation
- A traffic decline proves revenue loss
- AI absence equals a precise dollar value of lost pipeline
- A technical fix secures ranking growth
- Career-reported outcomes predict future performance
The audit creates a disciplined evidence base.
It helps leadership decide what to investigate and fix next.
Rakesh’s Operating Perspective
Rakesh’s reported experience across Dotcom-Monitor, Voxco, and Muvi supports a systems-level approach to organic growth.
At Dotcom-Monitor, he reports a 40% increase in AI Overview placement through GEO and entity architecture.
At Voxco, he reports a 320% increase in organic traffic, with organic inbound contributing more than 80% of total inbound pipeline.
At Muvi, he reports a 200% MQL-to-SQL uplift across eight micro-SaaS product lines supported by a 1,000-plus-term keyword architecture.
These outcomes should not be presented as universal benchmarks.
Their strategic value is the operating lesson:
Technical access
+
Product and category clarity
+
Buyer evidence
+
Structured content
+
Measurement discipline
=
A stronger organic growth system
The Enterprise AI-Invisibility Audit applies that logic to answer-engine representation.
AI visibility is not a new channel to bolt onto SEO. It is a test of whether your company is understandable, retrievable, and credible.
Frequently Asked Questions
Find Out Where Enterprise Buyers Lose You
Your company may be absent from the answers shaping buyer shortlists, even when your website ranks and your traffic appears stable.
Rakesh’s Enterprise AI-Invisibility Audit identifies:
- Missing commercial prompts
- Competitor default patterns
- Evidence gaps
- Technical retrieval failures
- Representation inaccuracies
- Weak content-to-pipeline connections
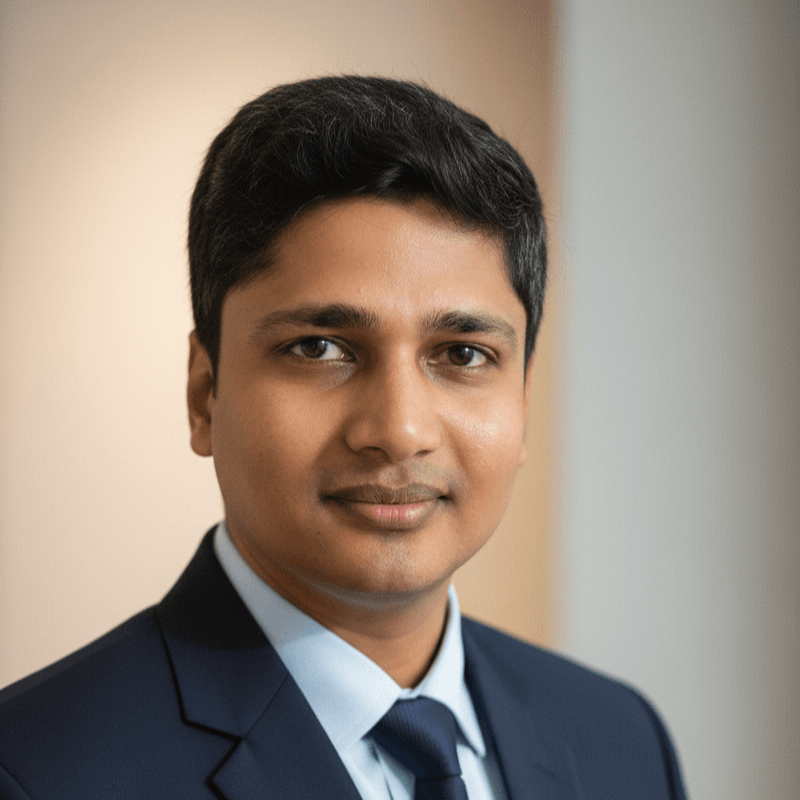
Rakesh Ranjan Samantaray
Head of SEO & B2B SaaS Growth Architect. Rakesh specializes in bridging the gap between technical architecture, organic demand, and AI Answer Engine Optimization (GEO). His frameworks help high-growth SaaS and enterprise teams structure their AI discoverability.